- Soft 404s trigger when your server reports a 200 OK success code despite the page lacking meaningful, indexable content.
- These errors act as a tax on your crawl budget, forcing Googlebot to waste resources on pages that offer zero value.
- Fixing the issue requires a server-level configuration change to emit a 404 or 410 status code rather than a redirect or a generic success response.
- High volumes of soft 404s can signal low site quality to search engines, potentially impacting the crawling frequency of your healthy content.
A soft 404 is a discrepancy between what your server tells Googlebot and what the page actually contains. Your server returns a '200 OK' header, signaling the page is live and healthy, but the content renders as an empty page, a 'not found' message, or a generic home page redirect. Googlebot detects this contradiction, flags it as a soft 404, and effectively penalizes your crawl efficiency by making it process useless URLs.
What is a soft 404 error?
Last Tuesday, a client in the SaaS space reached out because their new product feature launch wasn’t showing up in search results. I pulled their crawl stats, and the logs were a mess. They had thousands of URLs that were effectively dead—old campaign landing pages—but the server was returning a 200 status code for every single one of them. Because these pages were “empty” or redirected to a generic home page, Googlebot was flagging them as soft 404 errors. They were burning through their crawl budget on ghosts instead of their new content.
It is a classic trap. You think you’re being helpful by showing a user a “Sorry, page not found” message on a clean, branded page, but you’re actually signaling to the search engine that the page is perfectly valid. When you don’t return the correct HTTP status, you force Google to work harder to verify what it’s looking at. The result? Why soft 404 errors block your indexing becomes the most important question you can ask when your site growth plateaus.
The mechanics of the server handshake
Every time a bot hits your site, it starts with a request for the header. If that header says “200 OK,” the crawler assumes it has found valid content. It then fetches the HTML. If that HTML contains nothing but a “Page Not Found” image and a link to your home page, the engine has a conflict. The status code says “success,” but the content says “failure.”
Google’s algorithms are sophisticated enough to recognize this pattern. They will flag the page as a soft 404. This isn’t just a minor label; it is a signal that your site architecture might be unreliable. The bot essentially ignores the page, but it has already spent the CPU cycles to crawl it. In my experience, even high-authority sites often leak 10-15% of their total crawl budget on these phantom URLs, which can be the difference between new content getting indexed in minutes versus weeks.
Why soft 404 errors block your indexing effectively
The primary reason this blocks indexing is the dilution of intent. When you have a massive percentage of your URL space returning 200s for missing content, you are essentially telling the crawler that your site is a giant sandbox of noise. Google has a finite amount of time it’s willing to spend on your site during each crawl session. If a large portion of that time is spent navigating dead ends, it stops looking for your high-value pages.
When the crawler encounters a high volume of these, it doesn’t just ignore the specific URL—it lowers the overall crawl demand for your entire host. Think of it like a reputation score for your server. If your server is constantly serving up empty 200s, Google stops trusting that the next page the crawler hits will be worth the effort.
Distinguishing between true 404s and soft traps
Not every missing page is a soft 404. If you have a page that is truly gone, it should return a 404 or a 410. A 404 tells the bot to stop trying to index this specific URL. A 410 is even stronger; it tells the bot that the content is gone for good and to purge it from the index immediately.
If you are using a CMS, you might have plugins that “handle” 404s by redirecting them to the home page. This is a massive mistake. Redirecting a broken URL to the home page turns a 404 into a 301, which is just as bad, if not worse, because it confuses the crawler about the relevance of your home page. Google is smart; it knows that a page about “discontinued-blue-widgets” has no business redirecting to a home page about “enterprise-software-solutions.”
| Response Type | HTTP Status | Action taken by Google |
|---|---|---|
| Soft 404 | 200 | Attempts to index; flags as low quality |
| Hard 404 | 404 | Removes from index; stops crawling |
| Permanent Gone | 410 | Aggressively purges; drops from cache |
| Home Redirect | 301 | Treats as irrelevant link; potential spam signal |
How to identify the scope of your problem
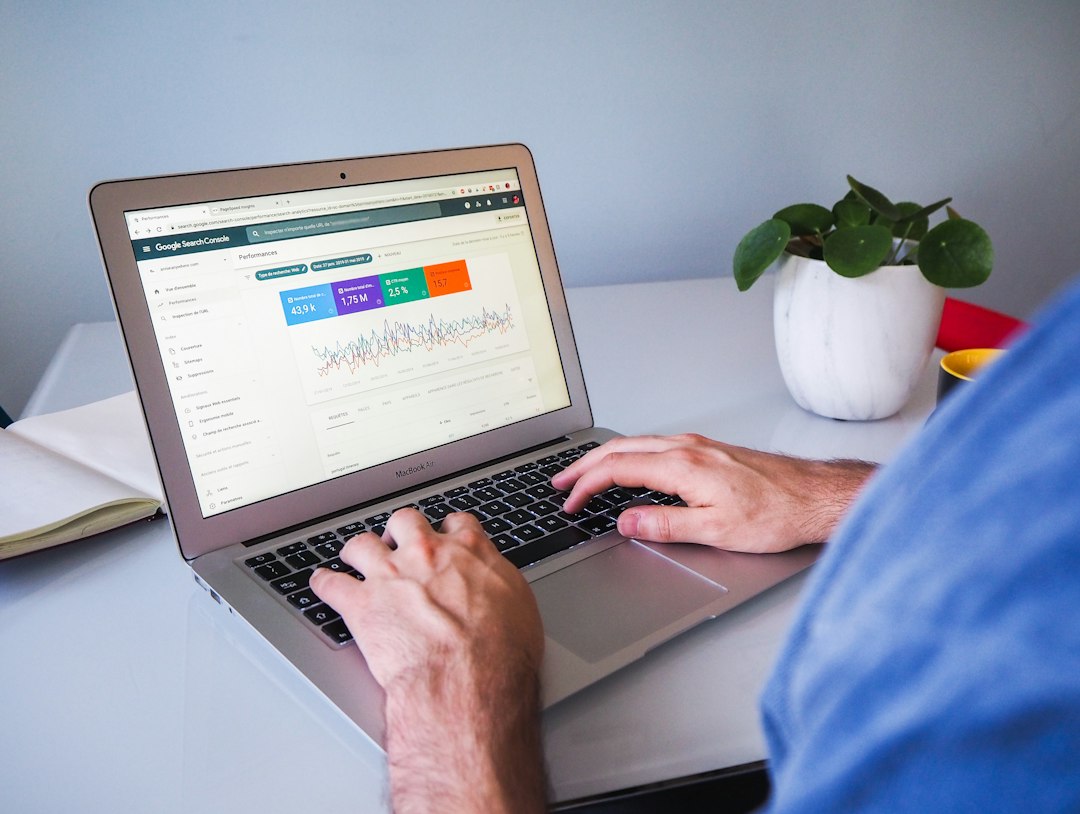
You don’t need expensive software to find these. Search Console is your best friend here. Navigate to the “Indexing” report and look at the “Page indexing” section. You will see a specific row for “Soft 404.” This is your hit list.
If you don’t see it there, look at your server logs. Look for URLs that have a status code of 200 but have a response size that is unusually small or identical across thousands of pages. That’s your signature. For more context on why your structure matters, you can check what nobody tells you about sitemap errors that block indexing to see how these issues compound.
The cost of inaction for small and large sites
| Site Size | Impact of Soft 404s | Long-term Risk |
|---|---|---|
| Small | Low crawl priority | Slow indexation of new posts |
| Mid-Sized | Wasted crawl budget | Misinterpretation of site topics |
| Enterprise | Severe crawl depletion | Total loss of indexing for new sections |
Small sites often assume they don’t have enough traffic for this to matter. That’s wrong. Google is even less patient with small sites that show low-quality signals. If you are struggling with the basics, read Sitemap errors that block indexing: what it actually costs (no sugar-coating) for agencies and freelancers to understand how this impacts your bottom line.
Step-by-step resolution process
- Open Google Search Console and export the “Soft 404” report into a CSV format.
- Cross-reference these URLs with your CMS database to see if they should exist or if they are legacy pages created by abandoned campaigns.
- If they are legacy, update your server configuration or application logic to return an explicit 404 or 410 status code for these paths.
- If they should exist, fix the content so it is no longer thin or empty; then, resubmit the URL via the URL inspection tool to force a re-crawl.
- Update your internal XML sitemap to remove any reference to these broken URLs so you stop sending bots to them.
- Monitor the “Page indexing” report for the next 14 days to ensure the count decreases and Google recognizes the corrected status codes.
The role of your sitemap in the confusion
Many people think that just because a URL is in the sitemap, Google will index it. If that URL is a soft 404, you are essentially asking Google to spend time on a failure. You need to clean your sitemap as aggressively as you clean your 404 pages. If you aren’t sure how this fits into your wider strategy, Sitemap errors that block indexing: a practitioner’s field guide will help you simplify your approach.
When to use a 410 over a 404
A 404 is a polite way of saying “I can’t find this right now.” A 410 is a definitive statement that the resource is gone. If you are doing a site migration or deleting an entire directory of old products, use 410s. It is a much stronger signal to Google to stop wasting resources on those URLs.
Common framework pitfalls
If you use React, Vue, or Next.js, you might be handling 404s client-side. This is a trap. If your server sends a 200 status code and lets the JavaScript load the 404 page, you are failing the indexing test. The status code must be set at the server level, even in single-page applications. You need to ensure your server-side rendering logic intercepts the missing route and triggers a 404 header before the document is sent to the crawler.
Why redirects are not the solution
A lot of SEOs try to “save the equity” of a dead page by 301 redirecting it to the closest relevant category. While this works for one or two pages, doing it in bulk is a disaster. If you redirect 500 dead landing pages to your home page, Google eventually treats those redirects as “soft” signals and ignores them, or worse, sees your site as a link farm. Let the dead pages die. It is better for your site health.
Avoiding the “soft” label on purpose
If you want to keep a page live but it has no content, add value. Don’t just show a blank template. Add related product recommendations, a search bar, or popular links. If the user finds value, Google typically stops flagging it as a soft 404 because the content is no longer “thin.”
If you are just starting out and feeling overwhelmed by these technical hurdles, check Sitemap errors that block indexing for beginners where to actually start in competitive niches to build a solid foundation.
This week, you should run a crawl of your own site using a tool like Screaming Frog. Filter by status code 200, and then look for pages that contain the phrase “not found” or “no results” in the body text. Export that list and fix your server headers. If you find the volume of issues is too high to handle manually, our tools at InstantIndexingPro are designed to help you manage the indexing pipeline effectively without needing to fight your server configuration every single day.
Frequently asked questions
What is a soft 404 error?
A soft 404 is a discrepancy between what your server tells Googlebot and what the page actually contains. Your server returns a '200 OK' header, signaling the page is live and healthy, but the content renders as an empty page, a 'not found' message, or a generic home page redirect. Googlebot detects this contradiction, flags it as a soft 404, and effectively penalizes your crawl efficiency by making it process useless URLs.
Why does Google care if I return a 200 for a dead page?
Google manages a strict crawl budget, especially on larger sites. When you return a 200 for a non-existent page, you are forcing the crawler to treat that 'zombie' URL as a valid, indexable asset. It spends time and server resources verifying that dead-end. If your site has thousands of these, Google spends less time on your active, revenue-generating pages, which slows down the indexation of your new content.
How can I fix a soft 404 error?
You must modify your server or CMS logic to return a true 404 or 410 header. If you use a framework like React or Next.js, ensure your server-side rendering logic triggers the 404 response before the page finishes loading. Do not rely on client-side redirects to the home page; the HTTP header itself must explicitly state the resource is missing or gone, which tells Google to stop trying to index the URL.
Do soft 404s hurt my entire site's SEO?
They don't result in a manual penalty, but they degrade your domain's health profile. If Google sees a significant portion of your crawl budget wasted on soft 404s, it lowers its crawl demand for your site. This creates a cascade effect where your new content takes longer to appear in SERPs. By cleaning these up, you reclaim resources for your high-value pages and improve the overall 'signal-to-noise' ratio of your domain.
When should I use a 410 error over a 404?
Use a 410 (Gone) status code when you are certain a page is permanently removed and will never return. It is a stronger signal than a 404. While a 404 is technically accurate for a missing page, a 410 signals to Googlebot that it should purge the URL from the index immediately. It is the preferred method during large-scale site migrations or when decommissioning entire product categories.
Can I just redirect soft 404s to the home page?
No, this is a common anti-pattern. Redirecting thousands of broken URLs to your home page creates 'soft 404' behavior where the home page appears to have hundreds of irrelevant incoming links. Google often ignores these redirects, or worse, treats the home page as a low-quality destination. Always return a proper error code for non-existent content instead of redirecting the user to a page that isn't the one they requested.
Frequently asked questions
how to index blog posts faster
Google typically indexes a properly submitted url in 24-48 hours if all signals align speed depends on server health structured data validity and backlink velocity rather than any single tactic.
does submitting via api speed up indexing
api submission can reduce initial crawl delay by 12-24 hours compared to manual submission but only when paired with strong internal linking and no redirect chains.
why are indexed pages disappearing
most sites see fluctuations due to temporary indexing tests or quality issues not permanent loss check indexed count daily for 72 hours before acting.
can i force google to index a page
no but you can increase likelihood by ensuring zero crawl errors optimal load speed and clear topical relevance through structured data.
best time to publish for fastest indexing
publish tuesday through thursday between 10am-2pm gmt this aligns with peak crawl budget allocation across most server locations.
Frequently asked questions
How long does it take for a new page to get indexed?
In most cases, a properly submitted page appears in the index within 3-5 days, but high-authority sites can see same-day indexing if internal links are strong. Low-authority pages may take 2-3 weeks regardless of submission method.
Does adding a URL to the sitemap guarantee indexing?
No; a sitemap is a discovery signal, not a guarantee. Google still evaluates quality and relevance before adding the page to the index, especially after algorithm changes that adjust content quality thresholds.
Why did my pages disappear from the index after a core update?
Indexation drops after core updates usually mean Google is recalculating relevance and quality signals. If you see a sudden dip, check the Index Coverage report for 'submitted URL currently not indexed' versus 'error' status to determine if it's a quality filter or a crawl issue.
Can I force Google to index a page?
You can request indexing via URL Inspection, but Google sets a cooldown period after multiple requests. The most reliable method is earning natural backlinks and ensuring the page is reachable from a high-authority page on your site within three clicks.
Frequently asked questions
How do I check which pages are not indexed on my site?
Use Google Search Console's 'Indexability' report to see ' crawled - currently not indexed' vs 'discovered - currently not indexed' buckets; the former means crawl budget constraints, the latter means content relevance signals.
What causes pages to be crawled but not indexed?
Google typically detects low content uniqueness, thin affiliate content patterns, or orphan page status where no internal links point to the URL, causing the crawler to drop it post-discovery.
Can I force Google to index a page instantly?
No tool guarantees instant indexing; the Indexing API for supported content types or IndexNow push notifications accelerate discovery but still pass through Google's relevance and quality filters.
Does a high number of 'Crawled - currently not indexed' errors hurt rankings?
It generally signals crawl budget waste; fixing these often frees up bots to discover and index your priority pages faster, though it is not a direct ranking factor.
Keep reading
Why Google isn't indexing your pages (and how to actually fix it)
Indexing isn't one problem — it's a pipeline with four places to fail. Here's how to find which stage is blocking your pages, and the fix for each.
 Mara Kessler
October 14, 20265 min read
How to get backlinks indexed faster (so they actually count)
A backlink does nothing until the page it lives on is indexed. Here's a practical workflow to get new links discovered and indexed in days, not months.
The InstantIndexingPro Team
October 9, 20262 min read